NeurIPS 2026
GeneralistJEPA
Generalizing Action-Conditioned Latent World Models with Video Model Rewards
Learn motion from video models.
Predict the future in latent space.
Code release forthcoming.
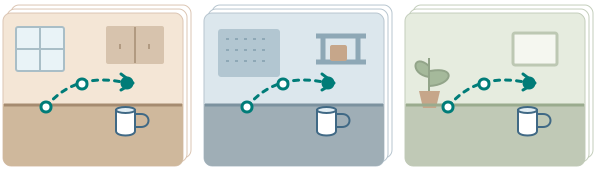
Shared action control Varied backgrounds
Inference predicts directly in latent space.Schematic clips, not experimental video outputs.
Hold the action control fixed. Generate different backgrounds. Use temporal changes as motion rewards for latent prediction.
Broad visual knowledge.
Limited action experience.
Large visual encoders learn from diverse videos. Their action-conditioned predictors often learn from much narrower experience: fewer tasks, objects, and motions.
GeneralistJEPA explores how motion priors from a frozen, controllable video model can broaden action-conditioned latent prediction.
Visual pretraining
V-JEPA 2
>1Mhours of internet video
Broad visual representations
encoder
Action post-training
V-JEPA 2-AC
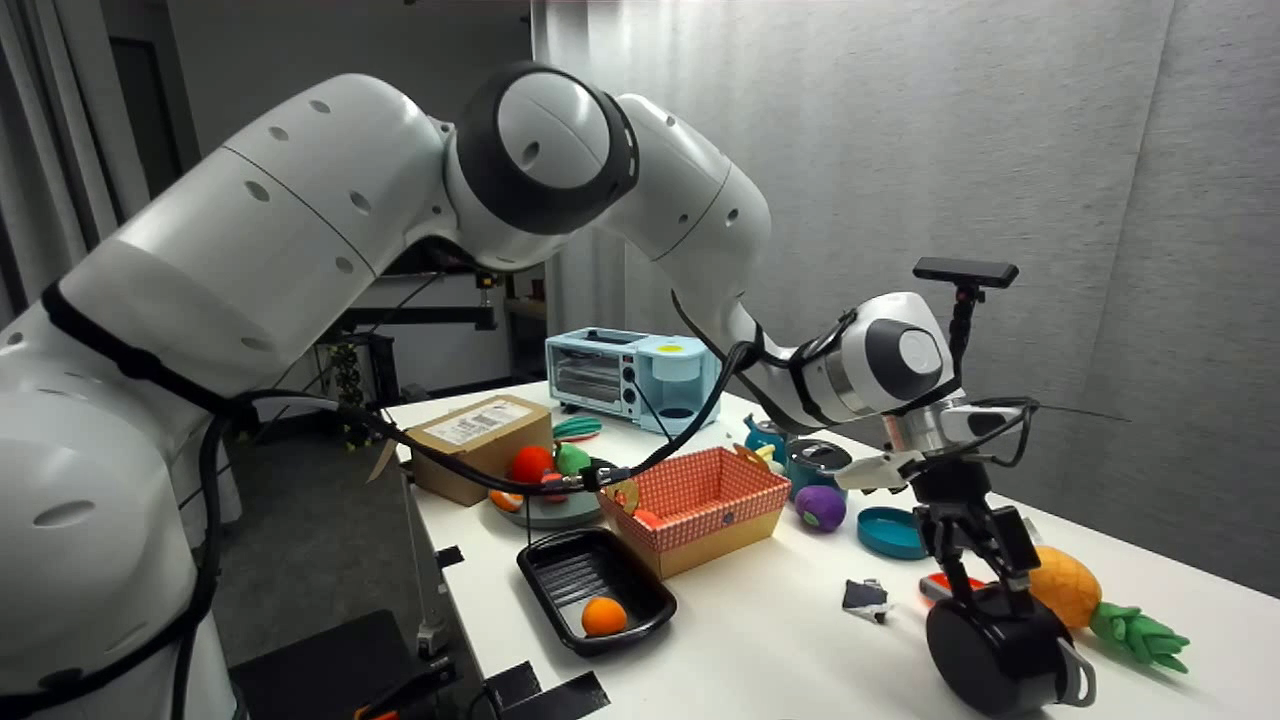
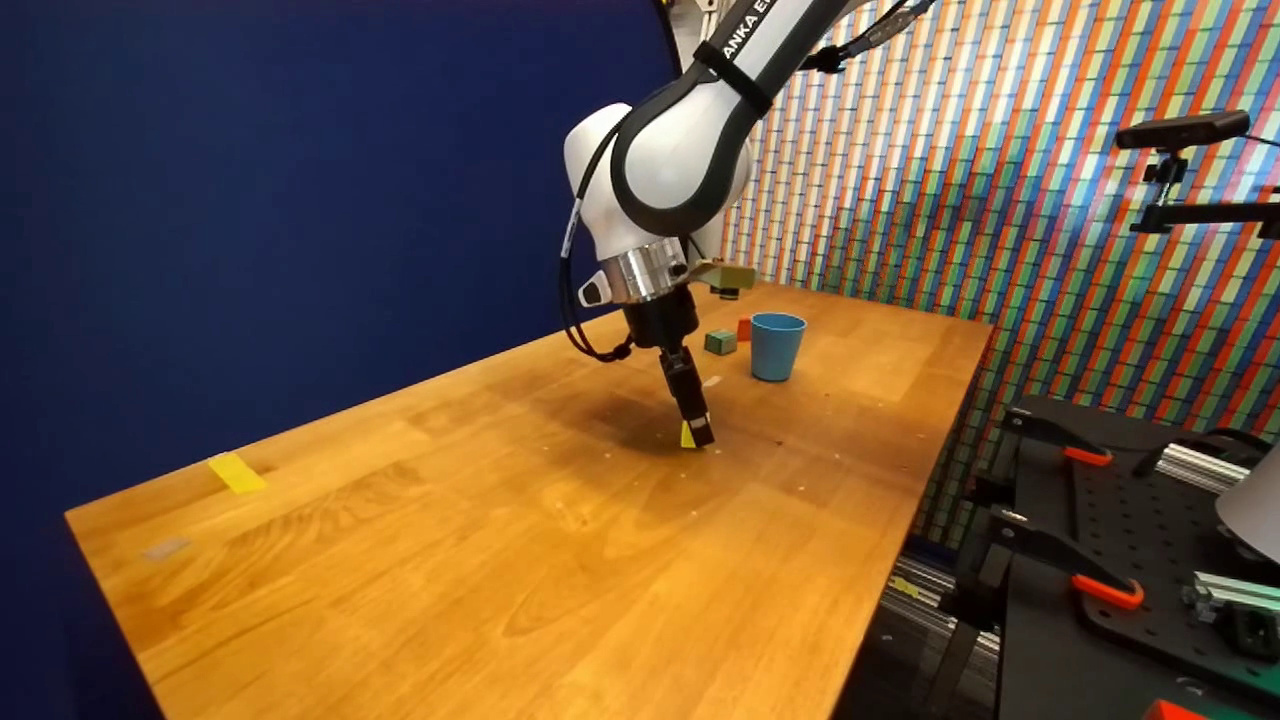
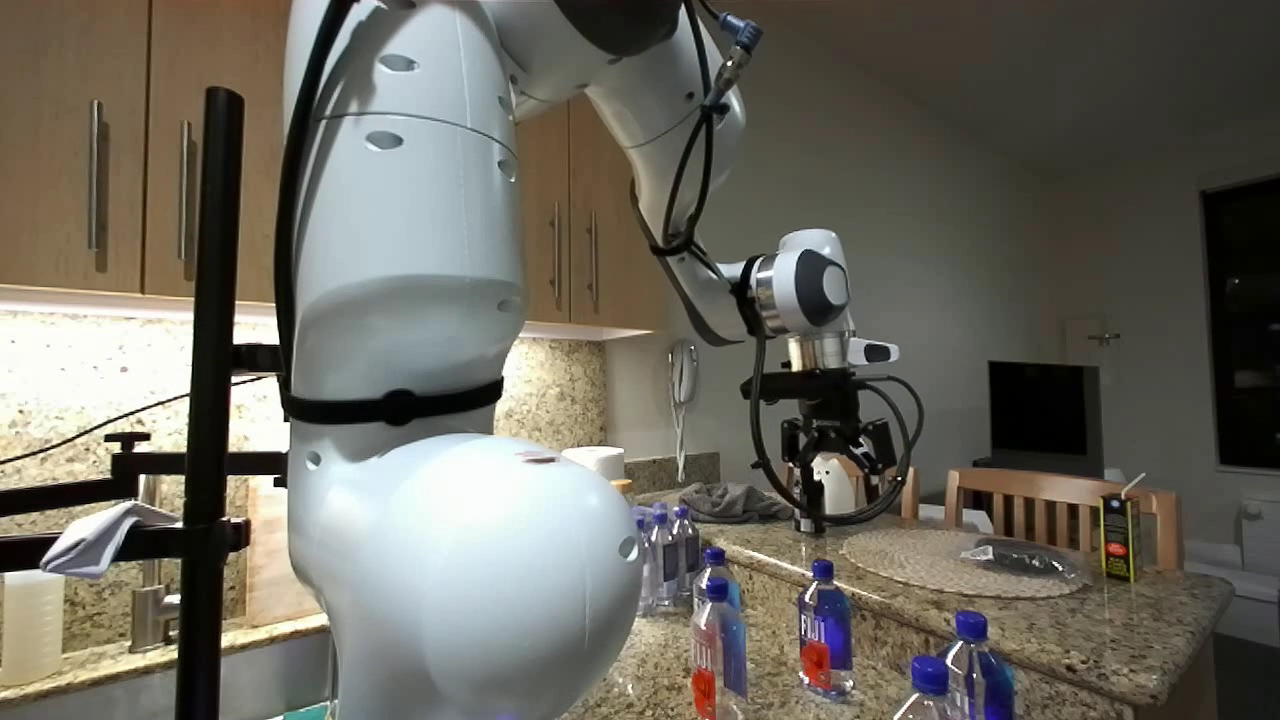
<62hours of robot video
Narrower action-conditioned experience
Can video-model motion priors broaden the predictor’s experience?
Teach motion. Keep latent prediction.
Generate varied backgrounds under shared action controls. Transfer temporal changes as motion rewards.

Direct prediction in latent space
Video generation and teacher-feature extraction happen offline. Inference uses the action-conditioned JEPA predictor to forecast future representations.
Generalization, measured.
Reported evaluations across three complementary settings.
Results on 111 categories, including 102 unseen categories
EgoDex official test set. No test-time adaptation.
111Evaluated categories
102Unseen categories included
2,525 / 3,243Unseen / total test episodes
Macro ADE ↓ Lower is better
Bars start at zero. Macro averages over 111 categories, including 102 unseen categories.
View all EgoDex metrics
| Method | ADE ↓ | FDE ↓ | PCK ↑ |
|---|---|---|---|
| V-JEPA 2 AC | 0.09011 | 0.09036 | 29.52% |
| DINO-WM | 0.11214 | 0.11522 | 15.34% |
| DINOv2 | 0.11627 | 0.11961 | 14.61% |
| V-JEPA 2 | 0.09154 | 0.09236 | 27.00% |
| GeneralistJEPA | 0.08995 | 0.08964 | 29.52% |
Read the comparison carefully. GeneralistJEPA reports the lowest ADE and FDE in this table. PCK is effectively tied with V-JEPA 2 AC. Metrics are macro-averaged over all 111 categories, including 102 unseen categories.
Action-conditioned robot pushing
Future latent prediction and action sensitivity on BAIR.
| Method | MSE ↓ | R@1 ↑ | Shuffle ↑ |
|---|---|---|---|
| V-JEPA + MLP | 5.3124 | 0.2188 | 0.0274 |
| V-JEPA Predictor | 4.6027 | 0.2474 | 0.0000 |
| GeneralistJEPA | 4.4828 | 0.3464 | 0.1910 |
| GeneralistJEPA w/Aux | 4.4782 | 0.3581 | 0.2078 |
Separate real-data protocol. BAIR uses no generated VWM bank. These results assess latent prediction and action sensitivity; they do not isolate the benefit of video-model motion rewards.
Physical contact from predicted futures
Object-contact readout on Physion.
| Method | Accuracy ↑ | AUC ↑ |
|---|---|---|
| DINO-WM | 0.6483 | 0.7049 |
| V-JEPA observed-only | 0.7383 | 0.8201 |
| V-JEPA AC Predictor | 0.7408 | 0.8213 |
| GeneralistJEPA | 0.7817 | 0.8622 |
Separate real-data protocol. Physion uses no generated VWM bank. The evaluation measures object-contact readout and does not establish video-reward gains on this dataset.
Source: accompanying research presentation, “Reported Results on Three Datasets.” Values are reported measurements, not an independent reproduction.
Research resources
A closer look at learning generalizable dynamics in representation space.
- Paper
- Read paper (PDF)
- arXiv
- Preprint link forthcoming
- Research code
- Project repository
Code release forthcoming - Qualitative videos
- To be added with the release
- Citation
- Download BibTeX
Cite this work
GeneralistJEPA at NeurIPS 2026.
@inproceedings{zhang2026generalistJEPA,
  title = {Generalizing Action-Conditioned Latent World Models with Video Model Rewards},
  author = {Zhang, Haichao and Li, Yijiang and He, Shwai and Le, Van Thanh and Vasconcelos, Nuno and Fu, Yun},
  journal={Advances in Neural Information Processing Systems},
  year={2026},
  url={https://openreview.net/forum?id=E6rncT8Glg}
}